
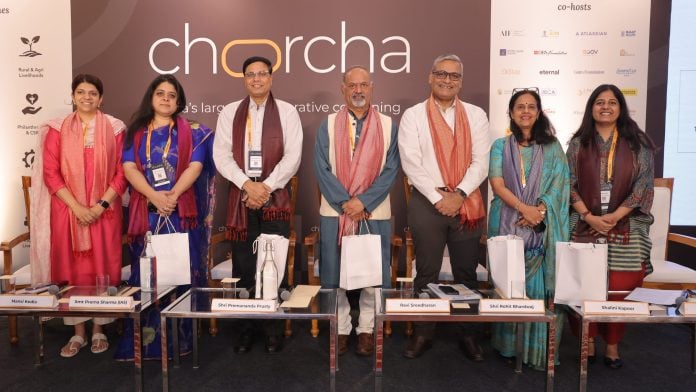
Delhi records the birth weight of every child born in the city. Used well, that single fact could show which neighbourhoods need more midwives and antenatal care. For years, though, this public data was available only as an annual PDF on the website of Delhi’s Directorate of Economics and Statistics (DES). Now DES is working with EkStep Foundation to change that, making birth and death records AI-ready. Premananda Prusty, Director of DES and Chief Registrar, who is accountable for all birth and death data recorded in Delhi, said, “We are mandated to release an annual report on births and deaths, and we upload it on our website in a PDF format which is accessible when one visits our website.This data that existed in silos was harmonized by breaking down PDF into organized, unique-ID datasets categorized by specific variables like area, delivery type, and gender. Standardization was applied by preparing comprehensive meta-data according to NMDS 2.0 Standards The outcome is a highly accessible, AI-readable format that enables the public, researchers, and policymakers to easily utilize the data for good governance.”
Ask a general-purpose AI whether low birth weight is a problem in Delhi and it will draw on the open web. The reply sounds plausible but helps no one: around 15 to 20% of urban Indian births may be low birth weight, it may say, quoting figures from the National Family Health Survey (NFHS) or the Health Management Information System (HMIS). But now that Delhi’s records can be queried, put the same question to them and you get an answer a health officer can use. 29% of all births in Delhi fall into the low birth weight category, out of the 87,874 recorded in 2024. Of those, no skilled attendant was present for 7,757 deliveries.
None of these figures names a single mother or child. They are aggregated, non-personal counts, the kind a department needs to plan. The numbers existed the whole time. What was missing was the work of making them usable.
Delhi’s problem is not an isolated one. India’s governments hold enormous quantities of data: land records, birth and death registers, scheme rolls, crop and market figures gathered across ministries and states. Very little of it can be found, read, joined or trusted well enough for a person, or a machine working for a person, to rely on. India’s National Statistics Office, which sits under the Ministry of Statistics and Programme Implementation (MoSPI) and has produced the nation’s official statistics on employment, household consumption, health and education for seven decades, confirmed this at a panel at charcha 2026, India’s largest collaborative convening for the development sector. Its senior representatives said, “Never before have we gathered so much data. Never before has the gap between data abundance and data readiness been so wide.” They added: “We are data rich but not data wise.”
Making one dataset usable is hard. Doing it across dozens of departments needs a method. Data DHARA, a framework published by EkStep Foundation (datadhara.ekstep.org) and set out in a consultative white paper, defines a seven-stage lifecycle for a single dataset, from identified and described, through interoperable and governed, to genuinely AI-ready. It works as a diagnostic. A department can place its dataset at one of the seven stages and see what the next one asks for. The method compounds as more departments use it, so the second dataset comes easier than the first and the tenth becomes routine.
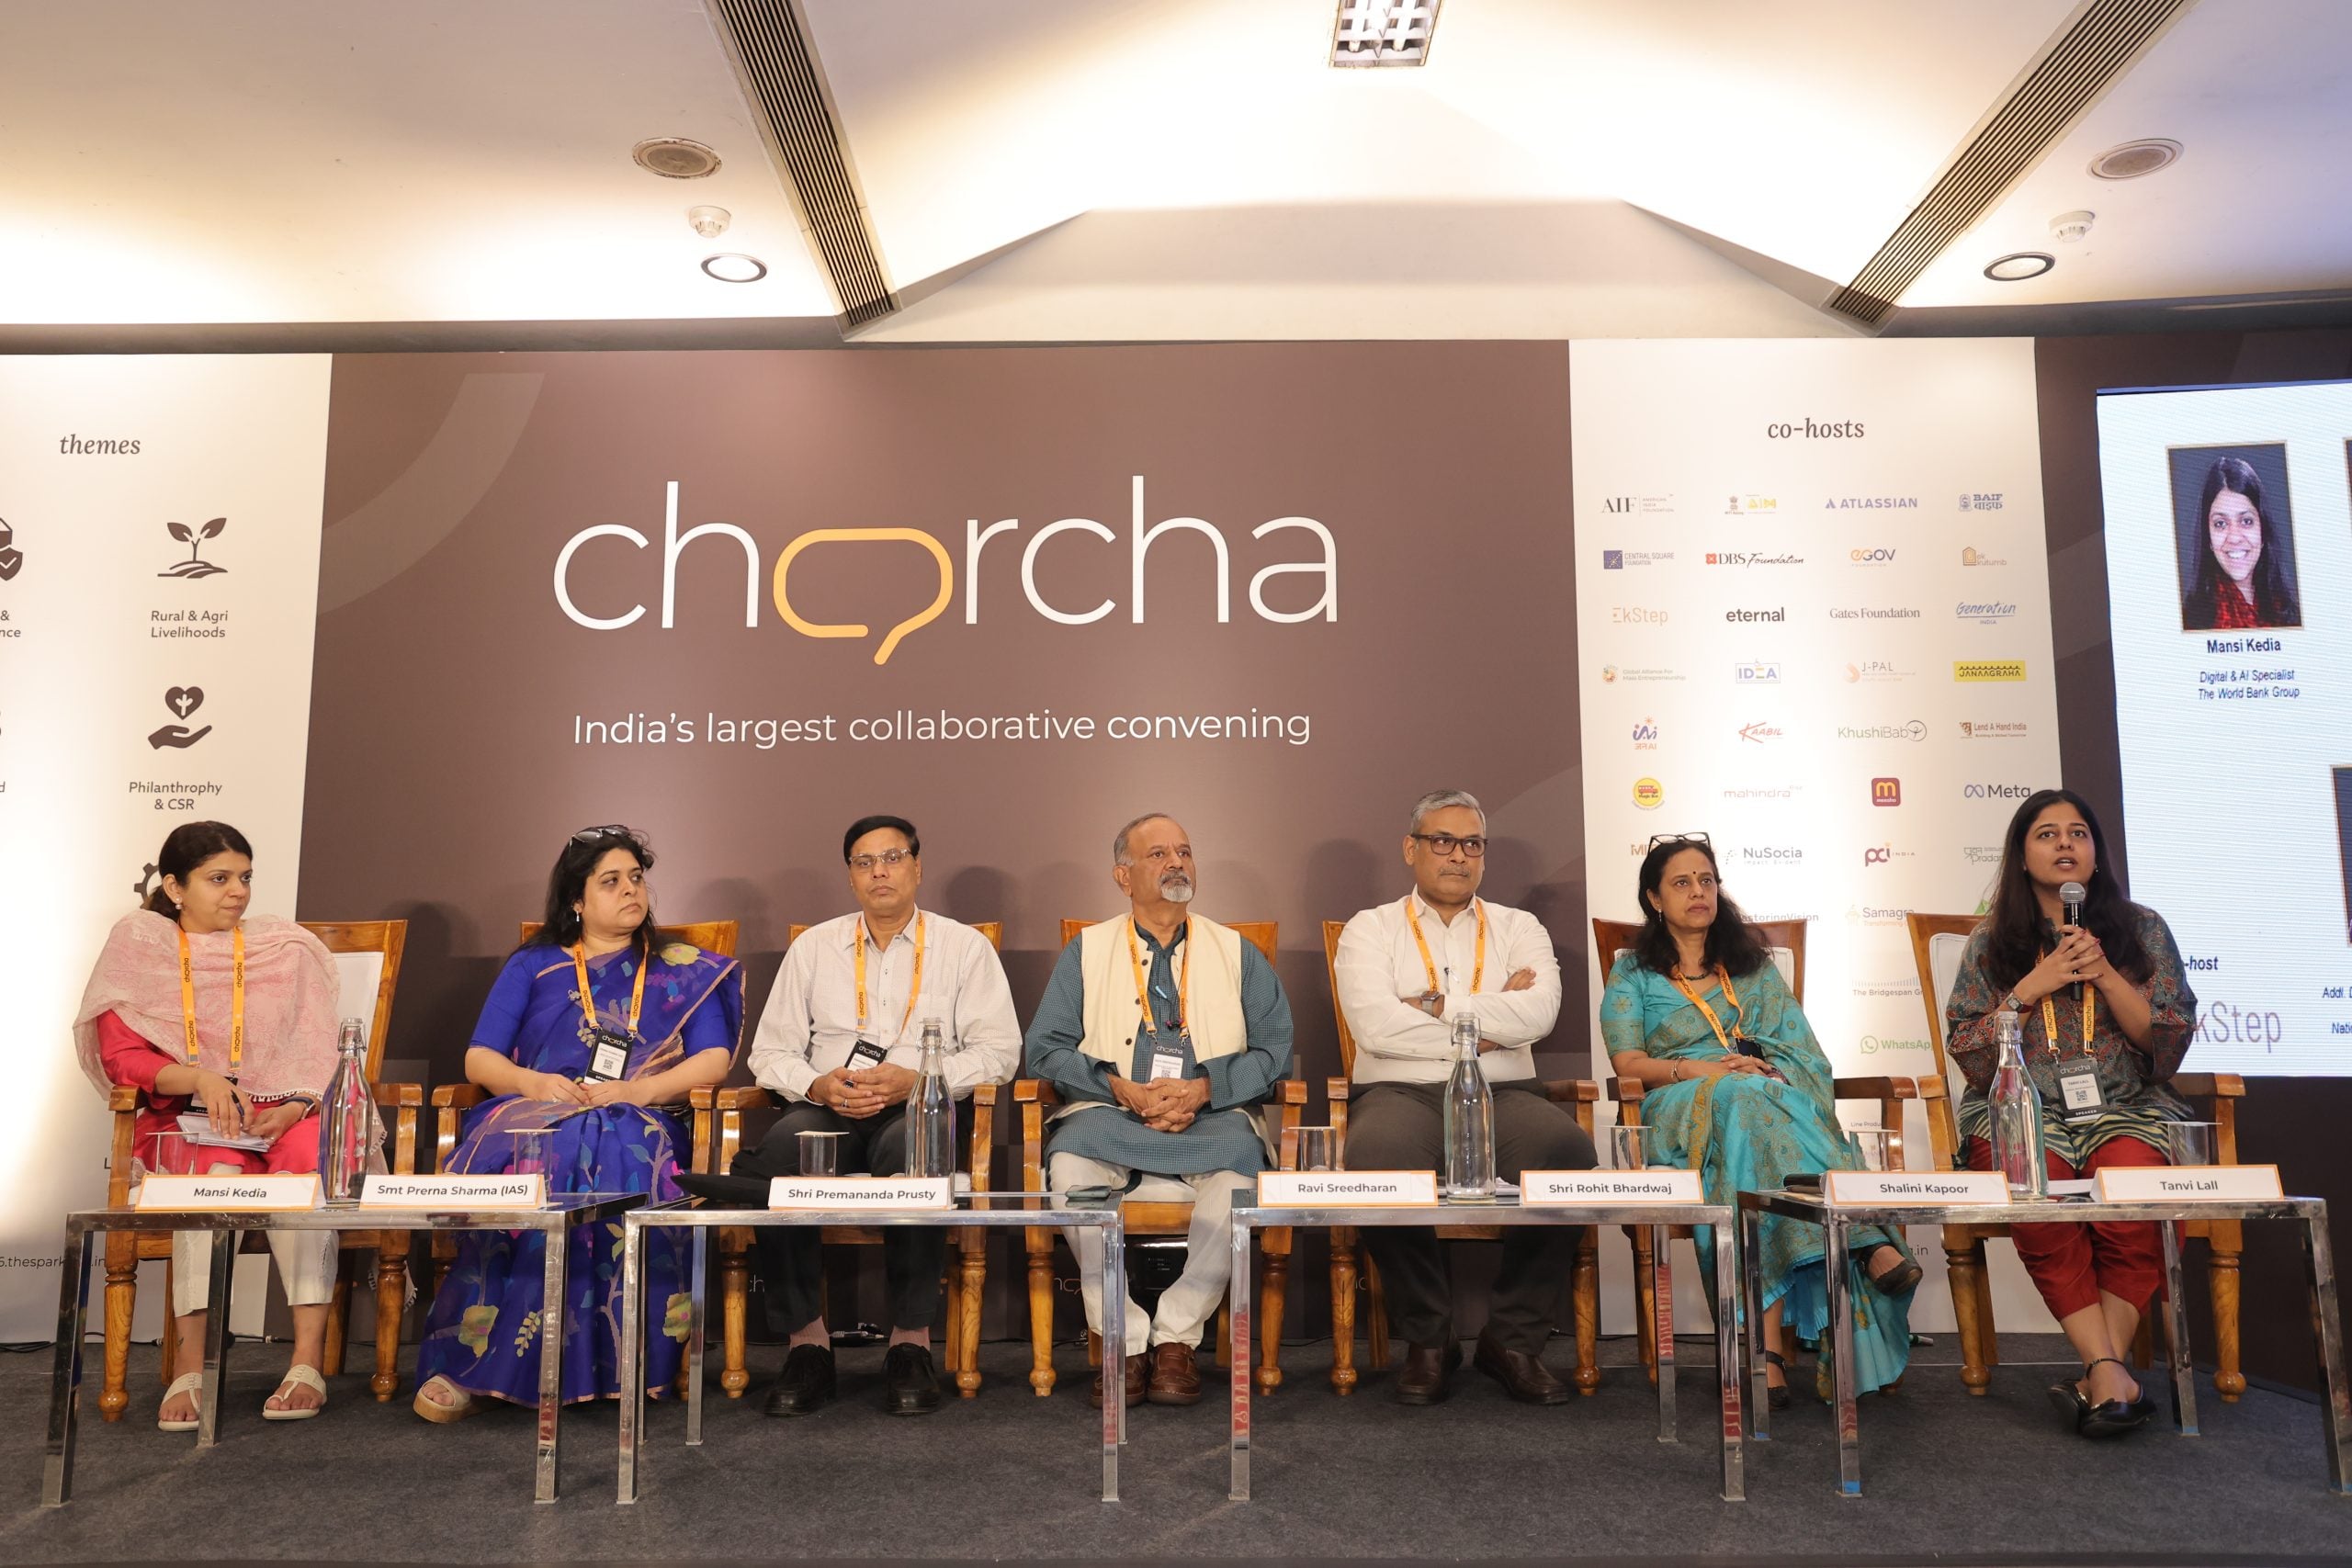
The same approach served a very different citizen in Uttar Pradesh. A woman in Hardoi who wants to open a cold-storage unit on her small plot, so farmers nearby can hold their produce instead of selling it cheap at harvest, once had to chase her answers across several hundred government orders held in more than 30 departments, with no one to search for her. Now she asks Nivesh Suvidha, an AI-enabled investment facilitator Invest UP runs across all 75 districts, in Hindi, in the words of the land record, using gata sankhya and bigha rather than plot numbers and hectares. It returns the rule that applies and a person to call. Building it meant studying roughly 14,000 past queries and mapping the approval journey across those departments, and the hardest part was not the software. The result, said Prerna Sharma, Additional Chief Executive Officer at Invest UP, came “not only through business re-engineering and technology, but a lot of change in mindset.” Every document had to be settled first: who owns it, who may publish it as the state’s answer, and who stands behind it when a citizen acts on it. A file being public on a website is not the same as the state standing behind it.
Departments that hold data hesitate for good reason. They worry about being blamed for records they do not fully understand, or about losing control of what they see as theirs. The toolkits are built for that. Know Your Dataset lets a department check a raw dataset and judge how far it can be trusted before anyone builds on it, then decide which datasets stay under national control and which are open to outside users under clear rules. A shared toolkit covers the remaining stages, and outside teams build on the result inside a governed sandbox. The department keeps ownership. Outsiders get access only on the state’s terms.
What Delhi did with its birth records and Uttar Pradesh did with its policies is the same move made twice: take data the state already holds and make it usable. AI is what makes this urgent now. For decades, data no one could use was a filing problem and little else. Once machines can read and connect these records, the same data can decide which scheme reaches a family, which loan is approved, which district gets a health team first. Whoever makes the data usable shapes what is built on it.
The larger stake here is sovereignty. An AI system has three parts: the chips that provide computing power, the models that do the reasoning, and the data the models are trained on and draw from. India buys most of its chips and models from a few foreign firms. The data about its own people is the one part it can own fully, and the part it has done least to secure. If India cannot reach and govern the records of its own population, it will depend on others to build the systems that make decisions from them. A country that cannot use its own data will not control what is made from it.
Viksit Bharat 2047 will be built from millions of small decisions, made in clinics, small businesses and homes across the country. Each one is only as good as the data behind it. India already holds that data. What is left is to make it usable, and to treat it as national infrastructure, a path already lit by the pioneering efforts of Delhi and Uttar Pradesh.
ThePrint is a media partner for charcha, organised by the*spark forum.
Also Read: Viksit Bharat 2047 — the state as platform, the civil servant as builder